Short answer up front: A high-performance growth team isn't defined by headcount, tooling, or how many OKRs you wrote last quarter. It's defined by four things: decision speed, shipping cadence, measurement honesty, and ownership depth. The quiz below scores your team across those four dimensions in about six minutes. Most seed-to-Series C teams we assess land between 28 and 44 out of 80 — which means they have the ambition of a high-performance team and the operating system of a committee.
We built this diagnostic because we run it on ourselves. At Growaton, our pods ship on a weekly cadence, and the failure modes we see in client teams are the same ones we had to engineer out of our own: unclear owners, experiments that stall in review, and dashboards nobody trusts. This quiz is the compressed version of the first 30 minutes of every growth diagnostic conversation we have.
How to use this quiz
Read each statement and score it honestly. Not aspirationally — honestly. Score based on what happened in the last 30 days, not what you intend to do next quarter.
| Score | Meaning |
|---|---|
| 0 | Not true at all. We don't do this. |
| 1 | Occasionally true. Depends who's involved. |
| 2 | Mostly true. Some friction, but it happens. |
| 3 | Consistently, reliably true. It's a system, not an effort. |
There are 20 statements across 4 sections. Maximum score: 80.
Best practice: Have three people score it independently — a founder, a growth lead, and an engineer. The variance between their scores is often more diagnostic than the scores themselves. If your founder scores 62 and your engineer scores 31, you don't have a performance problem. You have a visibility problem.
Section 1: Decision Velocity (0–15)
High-performance teams don't make better decisions than everyone else. They make faster decisions and correct faster. Slow decisions compound into slow quarters.
Score each 0–3:
- Any single person on the growth team can launch an experiment affecting under 10% of traffic without approval from someone more senior.
- When we disagree on a growth priority, we have a named tiebreaker and the disagreement is resolved within 48 hours.
- We killed at least one initiative in the last 30 days that wasn't working — and did it before its "official" end date.
- Our weekly growth meeting produces decisions, not status updates. Someone leaves with a changed plan.
- New hires make their first meaningful, unsupervised change to the product or funnel within their first two weeks.
What your Section 1 score means
- 12–15: Genuine decision velocity. Protect it as you add headcount — this is the first thing that dies at 25 employees.
- 7–11: You're negotiating instead of deciding. Usually a symptom of undefined decision rights, not bad people.
- 0–6: Every decision routes through the founder. Your growth rate is capped by one person's calendar.
The pattern we see most: teams with strong talent and weak decision rights. Research on organizational decision-making from McKinsey found that respondents who said their organizations made fast, high-quality decisions were more than twice as likely to report strong financial results — and that ineffective decision-making consumes an enormous share of managers' time. Speed isn't recklessness. Speed is the product of clarity about who owns what.
Section 2: Shipping Cadence (0–15)
Growth is a function of how many quality shots you take. Our experiment velocity math is unforgiving: if your win rate is 20% and each win moves a metric 5%, you need roughly 20 tests to compound a 20% lift. At two tests a month, that's ten months. At two tests a week, it's under three.
Score each 0–3:
- Something user-facing shipped to production in each of the last four weeks.
- The gap between "we decided to test this" and "it's live" is under 10 working days for a standard experiment.
- We maintain a prioritized experiment backlog that's actively groomed — not a graveyard of stale ideas in a Notion doc.
- Engineering capacity for growth work is committed and protected, not scavenged from whatever's left after the roadmap.
- We ship small. Our median change is measured in days of work, not sprints.
What your Section 2 score means
- 12–15: You have a real growth engine. Your constraint is probably idea quality, not throughput.
- 7–11: The classic mid-range. You ship, but in bursts tied to individual heroics rather than a cadence.
- 0–6: You're doing growth projects, not growth. Every experiment requires re-negotiating for engineering time.
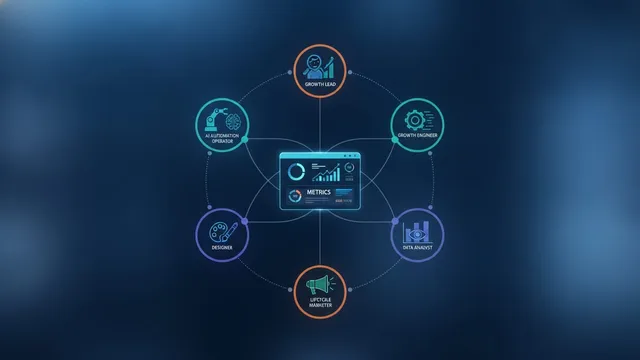
Section 2 is where most seed–Series B teams score lowest, and the reason is almost always structural: growth ideas live in marketing, execution capacity lives in engineering, and nobody owns the handoff. That gap is the single most common thing our pods eliminate in the first 30 days — not by hiring more people, but by putting design, engineering, data, and marketing into the same accountable unit.
Section 3: Measurement Honesty (0–25)
This section is weighted heaviest because it's where self-assessment is least reliable. Teams believe they're data-driven. Then you ask what their activation rate was last Tuesday and get three different numbers.
Score statements 11–15 on 0–3, then add the bonus question below.
- We have one agreed definition of activation, and every dashboard uses it.
- Any team member can pull the numbers they need without filing a request with a data person.
- We know our LTV:CAC ratio and CAC payback period by acquisition channel — not just blended.
- We write down a hypothesis and a success threshold before an experiment launches, and we compare results against it afterward.
- When an experiment fails, the learning gets documented somewhere the next person will actually find it.
Bonus (0–10): Rate your confidence that the number on your primary growth dashboard is correct right now, on a scale of 0 to 10. Be honest. Most teams say 9 and mean 5.
What your Section 3 score means
- 20–25: Rare. You've invested in data infrastructure and it's paying off in decision quality.
- 12–19: You have data but not truth. Numbers exist; trust doesn't. Expect debates about whether the number is real to consume more time than debates about what to do.
- 0–11: You are optimizing on vibes. Any growth you achieve here is unattributable and therefore un-repeatable.
A hard-earned observation from running diagnostics across SaaS, fintech, and marketplace clients: measurement debt is more expensive than technical debt. Technical debt slows you down. Measurement debt sends you confidently in the wrong direction for a full quarter. If you score under 12 here, fixing instrumentation before running more experiments will produce a better return than any single test on your backlog. It's why our 4-phase framework puts Diagnostics and Measurement before Conversion and Scale — the sequence isn't arbitrary.
Section 4: Ownership Depth (0–25)
The hardest dimension to fake and the hardest to build. Ownership is what happens when nobody's watching, when the metric dips on a Friday, when the obvious fix is outside someone's job description.
Score statements 16–20 on 0–3, then add the bonus question below.
- Every top-level growth metric has exactly one named human owner — not a team, not a committee.
- In the last month, someone on the team fixed a problem that wasn't in their remit and didn't ask permission first.
- People on our team say "I own that" and "I got that wrong" in roughly equal measure.
- We have a documented operating rhythm — weekly, monthly, quarterly — and it runs whether or not the founder is in the room.
- Senior people actively mentor junior people as part of the job, not as a favor.
Bonus (0–10): If you removed your single strongest operator for four weeks with no notice, how much of the growth function would keep running? Score 0 for "nothing" and 10 for "almost everything."
What your Section 4 score means
- 20–25: You've built a culture, not just a team. This is the moat.
- 12–19: Ownership exists but concentrates in one or two people. You're one resignation away from a stall.
- 0–11: You have employees executing tasks. Nothing wrong with that — but don't expect the outcomes of an ownership culture.
The single best proxy for ownership depth is that bonus question. When we've run this with founders, the average answer is around 4. Founders consistently underestimate how much of their growth function is load-bearing on one person — and it's rarely the person with the most senior title. Gallup's long-running engagement research consistently shows that only about one in five employees worldwide is engaged at work, which is a useful reminder: high ownership is not the default human state. It's engineered through role clarity, feedback, and consequence.
Scoring: what your total means
Add all four sections plus both bonus questions. Total out of 80.
| Score | Tier | What's actually going on | Highest-leverage next move |
|---|---|---|---|
| 65–80 | Compounding | You have a genuine growth engine. Velocity, truth, and ownership are all systems rather than efforts. | Raise the ambition of your bets. Your constraint is idea quality and market surface, not execution. |
| 50–64 | Capable | Strong in two dimensions, structurally weak in one or two. Growth is real but jagged. | Fix the lowest-scoring section only. Don't run a full transformation — repair the bottleneck. |
| 35–49 | Constrained | The most common tier. Talented people inside an operating system that leaks velocity at every handoff. | Cut cross-functional handoffs. One accountable unit owning idea→ship→measure beats four coordinated departments. |
| 20–34 | Stalled | Growth is founder-dependent and unattributable. Effort is high; compounding is near zero. | Instrument first. Establish a single source of truth and one weekly shipping ritual before adding anything else. |
| 0–19 | Pre-system | Not a criticism — often correct for pre-PMF companies. But you don't have a growth team yet; you have a group of people doing growth-adjacent work. | Name owners. Pick three metrics. Ship weekly. Nothing more sophisticated until those hold. |
The diagnostic pattern worth knowing
Score shape matters more than score total. Three shapes we see constantly:
High velocity, low measurement (Section 2 strong, Section 3 weak). You ship a lot and learn little. Feels productive. Compounds nothing. Fix: instrumentation and pre-registered hypotheses. Cheapest fix on this list.
High measurement, low velocity (Section 3 strong, Section 2 weak). Beautiful dashboards, glacial shipping. Usually an engineering-capacity problem disguised as a prioritization problem. Fix: protected, committed growth engineering capacity.
High everything, low ownership (Sections 1–3 strong, Section 4 weak). The most fragile shape. Performance is riding on two heroic operators. It looks like a high-performance team right up until one of them leaves. Fix: distribute metric ownership and build mentoring into the job description, not the nice-to-haves.
Turning your score into 30 days of action
Whatever your total, the sequence is the same: fix your lowest section first. Improvement in growth teams is bottleneck-driven, not average-driven. Raising a 22 to a 24 in your strongest dimension changes nothing.
If Decision Velocity is lowest
Write a one-page decision-rights document. For each recurring decision type — copy changes, pricing tests, new channel spend, onboarding flow changes — name the single decider and the threshold above which it escalates. Publish it. Most teams discover that half their bottlenecks were assumed approvals nobody actually required.
If Shipping Cadence is lowest
Commit a fixed percentage of engineering capacity to growth work and defend it in writing. Then shrink your unit of work: if the median experiment takes three weeks, you're testing bundles, and you can't attribute the results anyway. Break them apart.
If Measurement Honesty is lowest
Pick one metric — activation is usually the right choice — and drive it to a single agreed definition with one owner and one source of truth. Do not touch the other twelve metrics until that one is trusted. Then run the same play on the next.
If Ownership Depth is lowest
Assign every top-level metric to one named human this week. Not a team. A human. Then introduce a weekly ritual where each owner reports their number and their next action in under two minutes. Ownership becomes real when it's public and recurring.
Where an embedded pod fits — and where it doesn't
Honest framing, since this is our business: bringing in outside help is the right move for some scores and the wrong move for others.
Probably not yet (0–19, pre-PMF): You need product-market fit, not growth velocity. Outside growth capacity applied to an unvalidated product burns money faster and teaches you less. Come back when retention holds.
Strong fit (20–49): This is where an embedded pod does the most work — not because your team is bad, but because the gap is structural. Handoffs between marketing, product, engineering, and data are where velocity dies, and you can't fix a handoff problem by hiring one more specialist on either side of it. When we at Growaton drop a pod into a Constrained-tier team, the first 30 days are almost always measurement and cadence, not clever tactics. Founders expect us to arrive with growth hacks. We arrive with instrumentation and a weekly shipping ritual, because that's what makes everything after it compound.
Selective fit (50–64): You don't need a full pod. You need a specific workstream — usually growth engineering capacity or analytics infrastructure — plugged into an operating system that already works.
Probably not (65–80): You've built the thing. Use outside help for surge capacity or genuinely specialist skills, not for operating discipline you already have.
If you scored in the 20–49 range and want a second opinion on which of the four dimensions is actually your bottleneck, that's exactly what a free growth diagnostic conversation is for — 45 minutes, your numbers, no deck. And if you'd rather see how this plays out in practice first, our case study library documents the before-and-after on teams that started in the Constrained tier.
The uncomfortable takeaway
Most teams that score poorly on this quiz aren't underperforming because of the people. They're underperforming because the operating system around the people leaks velocity at every handoff — and because nobody has been given permission to own an outcome end-to-end.
That's fixable. It's fixable in weeks, not quarters. But it requires accepting that "we need to hire a growth person" is usually the wrong diagnosis. You more likely need clearer decision rights, protected shipping capacity, one trustworthy number, and one named owner per metric.
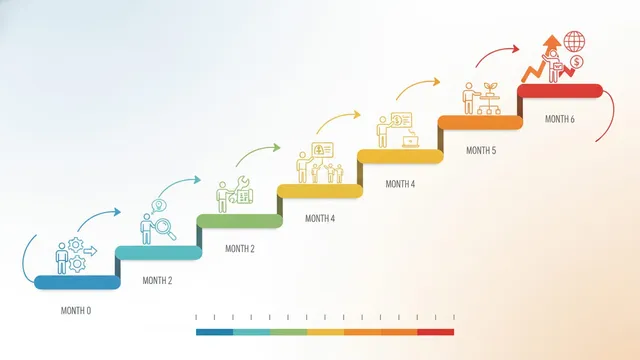
Take the quiz again in 90 days. If the total hasn't moved at least 8 points, you changed intentions instead of systems.